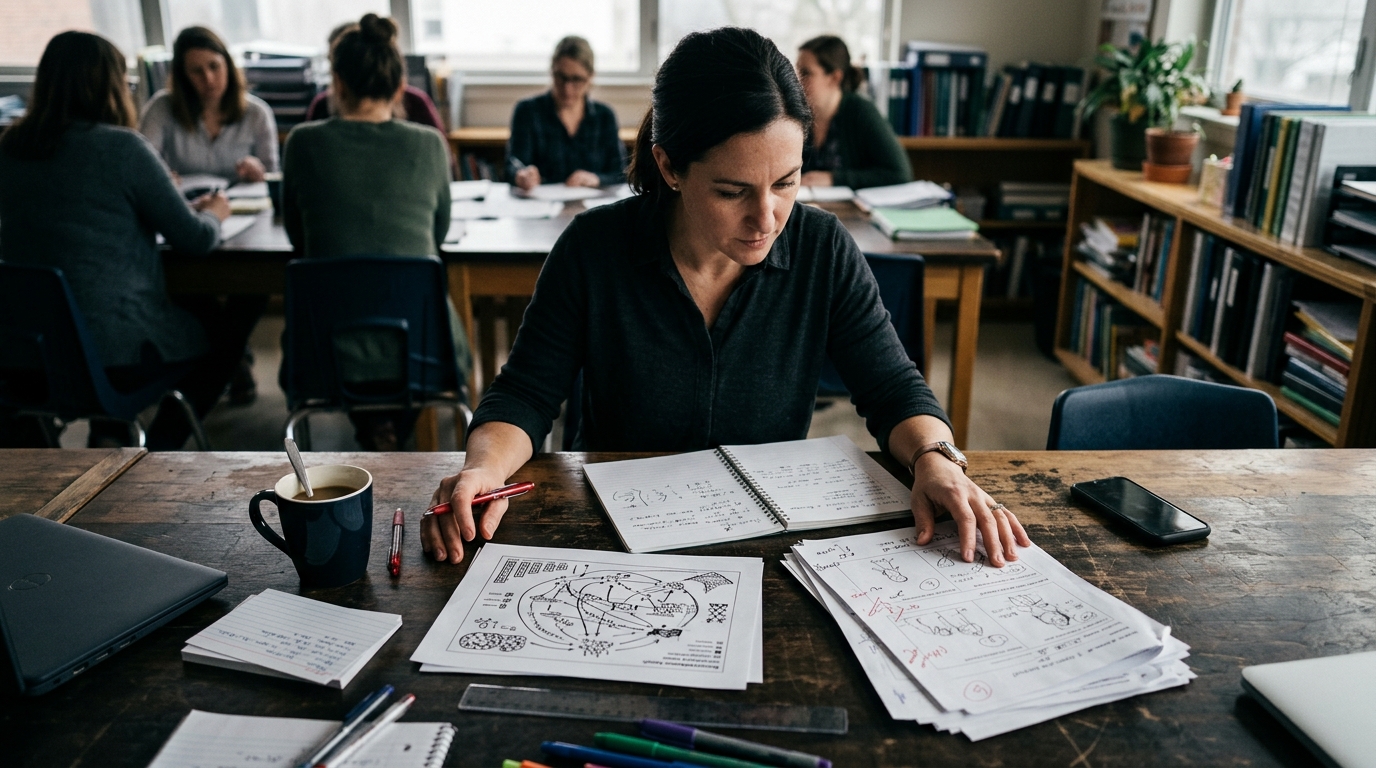
At 6:12 on a Tuesday morning, Lena Ortiz, a fictional eighth-grade science teacher, asks an AI assistant for an activity on food webs and invasive species. She specifies three goals: analyze, evaluate, and create.
The response looks excellent. Students will examine a population graph, evaluate two management options, and create a recommendation for a local conservation board. The directions use all the right vocabulary. There is a driving question, a rubric, and a suggested extension.
Lena reads the activity as a student before saving it. First, students match six terms to definitions. Then they select the graph that shows a trophic cascade. The two management options already include their advantages and disadvantages. The rubric supplies the criteria for evaluation, and the final recommendation can be copied from a model paragraph.
The worksheet mentions higher-order thinking at every turn. It requires very little of it.
Lena’s problem is common in AI curriculum design: a generated activity can sound cognitively ambitious while quietly doing the thinking for students. Bloom’s vocabulary is easy to add. The mental work those words describe is harder to design and verify.
Start with the mental work, not the Bloom label
Bloom’s Taxonomy is a useful planning vocabulary, not a quality seal. Benjamin Bloom and his colleagues published the original framework in 1956. Lorin Anderson, David Krathwohl, and others revised it in 2001, naming six cognitive processes: remember, understand, apply, analyze, evaluate, and create. The revision also described different kinds of knowledge, including factual, conceptual, procedural, and metacognitive knowledge.
For anyone searching for “Blooms taxonomy AI,” the practical distinction is simple: the taxonomy names the intended process; the student artifact reveals whether that process occurred.
Begin by specifying what students must decide, infer, or justify. An objective such as “Students will analyze how a species change affects an ecosystem” leaves too much hidden. A more useful version might read: Given two population graphs and a food-web diagram, students will make a claim about the likely cause of the change, cite two data points, explain the causal link, and identify evidence that could disprove their claim.
That objective gives AI something more precise to work with, but its main value is for the teacher. It identifies the evidence of thinking. A student who circles the correct graph has not necessarily analyzed anything. A student who selects a graph, connects it to the food-web relationship, and explains why a competing explanation is weaker has made the reasoning visible.
Lena rewrites her own objective before asking for another draft. The phrase analyze stays, but it no longer carries the whole burden.
Audit the verb against the evidence
A higher-order verb can sit on a low-demand task. Students can “analyze” a poem by highlighting a metaphor the teacher already identified. They can “evaluate” a policy by choosing from options whose criteria are printed beside them. They can “create” a poster by arranging supplied facts and images without making a substantive decision.
AI systems reproduce this problem easily because instructional language is full of familiar patterns. If a prompt asks for an activity aligned to evaluate, the output may include the word evaluate without changing what students actually have to do.
Run three quick tests on any generated activity:
- Remove the Bloom label. Read only the directions. What mental operation is genuinely required?
- Look for the shortcut. Can a student finish by matching terms, copying a model, or selecting an answer already supported by the materials?
- Name the artifact. Where will the student’s reasoning appear—in a comparison, explanation, annotated source, decision memo, or revision?
Webb’s Depth of Knowledge framework offers a useful second lens. Bloom’s Taxonomy describes the kind of cognitive process a task intends to involve. Depth of Knowledge asks about the complexity of the situation, the amount of strategic reasoning, and whether students must connect ideas or transfer them. The two frameworks complement each other, but they are not a single score. A task can ask students to evaluate an option while supplying every criterion needed to make the choice. Its label may sound advanced even when its strategic demand is narrow.
Lena prints her original worksheet and covers the taxonomy words with sticky notes. The remaining directions expose the weakness immediately. Every difficult decision has been made in advance. She replaces the two tidy management options with conflicting evidence and asks students to decide which claim the data support, then defend that decision.
Ask AI to expose the shortcut
A more reliable use of AI is to ask it to criticize the intended thinking before it writes a polished activity. For AI curriculum design, that change in role matters. The teacher supplies the learning goal and evidence; the model looks for ambiguity, missing prerequisites, and easy ways around the reasoning.
Lena uses a prompt like this:
Act as a curriculum critic, not a lesson writer. The goal is: Given two population graphs and a food-web diagram, students will make a causal claim, cite two data points, explain the link, and identify evidence that could disprove the claim. Students are in Grade 8 and know basic food-web vocabulary. Review the draft task and provide: the decisions students must make, the reasoning a student could skip, the easiest shortcut, two likely misconceptions, and what weak, adequate, and strong responses would show. If the task does not require genuine analysis or evaluation, say so and revise it. Do not use student names, student work, or invented research sources.
The prompt asks for a student-action trace rather than a decorative lesson. It also gives Lena a way to inspect the output. If the supposed strong response contains only a definition and a copied data point, the task has not produced the evidence she needs.
Before students see the generated material, Lena solves it herself. She writes one plausible wrong answer, one incomplete answer, and the response she would accept as strong. She checks the graphs, vocabulary, reading load, source material, and any claims the system introduced. If an accommodation changes the reasoning task into a recognition task, she revises the accommodation rather than accepting it automatically.
That review takes time. Depending on the activity, it may add 20 minutes to planning, and for a five-minute exit check it may be unnecessary. AI does not remove professional judgment; it can move judgment later in the process, when a teacher is tempted to trust a polished draft. Student names and identifiable work also have no place in a general-purpose prompt. A fictionalized example is enough to test the structure.
Scaffold upward, then read the work
The most demanding activity in Lena’s revised sequence begins with four ordinary recall items. That is deliberate.
The revised taxonomy is often drawn as a staircase, but Anderson and Krathwohl did not prescribe a fixed lesson order. Students may need factual and conceptual knowledge available in memory before they can reason with it. John Sweller’s cognitive load theory explains why a novice faced with a blank, complicated task can spend working memory on finding terms and interpreting instructions instead of examining the evidence. Research by Henry Roediger and Jeffrey Karpicke also gives retrieval practice a useful place in preparation for later learning.
Lena’s sequence is short: students first retrieve the food-web terms and predict the immediate effect of a population change. She then models one graph interpretation aloud. Students work individually on a new case with conflicting evidence. Finally, they write a claim-evidence-reasoning response and name one additional measurement that would test it.
The first AI draft suggested that students create a public-awareness poster. Lena keeps that possibility for a later extension but does not mistake the format for the thinking. Her core artifact is a one-page decision memo. It requires a claim, two accurate references to the data, an explanation of the causal mechanism, and a condition that would change the student’s mind.
This is one of the less intuitive lessons of Bloom’s Taxonomy and AI: more openness can produce less thinking. A blank page asks students to choose a topic, format, sources, and argument at the same time. Those choices may consume attention without improving the disciplinary reasoning. A constrained task can demand more thought when its constraints force students to compare, justify, and revise.
A higher Bloom level does not always mean better learning. The framework is not a precise measurement scale for student cognition, and its categories do not guarantee transfer. The approach fails when students lack the prerequisite knowledge, when the rubric rewards polished language instead of reasoning, or when the teacher treats the AI’s classification as an assessment result. For a simple fact check, forcing an elaborate higher-order task adds time and can obscure the skill being checked.
The final test is the student work, not the generated objective. Lena expects some students to cite two correct numbers and still draw an unsupported conclusion. That result tells her where the causal explanation needs more modeling. She can then revise the next activity around that specific gap instead of asking AI for another broadly “rigorous” worksheet.
Before Friday, take one AI-generated activity from your planning folder and cover its Bloom labels. Mark every place where students must make a decision, defend it with evidence, or revise an idea. If you cannot find three such moments, change the task before changing the label—and keep the revised version as your own professional work.